A guardrail is a dependency on the hot path
Every inline check adds time to a request that a person or an agent is waiting on. If the check calls a model, it also adds a line to the inference bill, and that line scales with traffic, not with attacks. Security teams are rarely asked for a latency budget, so they rarely have one. The first conversation about it usually happens when a product team measures the slowdown and asks for the guardrail to be switched off.
Treat each check like any other service dependency. It has a cost per call, a latency distribution, a failure mode, and a decision about what happens when it is slow or down. The design question is not whether to run a model judge, but which traffic needs one and how little of it you can send.
Agents raise the stakes. A chat turn is one request. An agent task can be twenty model calls and tool calls in sequence, and per-hop overhead compounds across the task.
Order checks by cost: the detection cascade
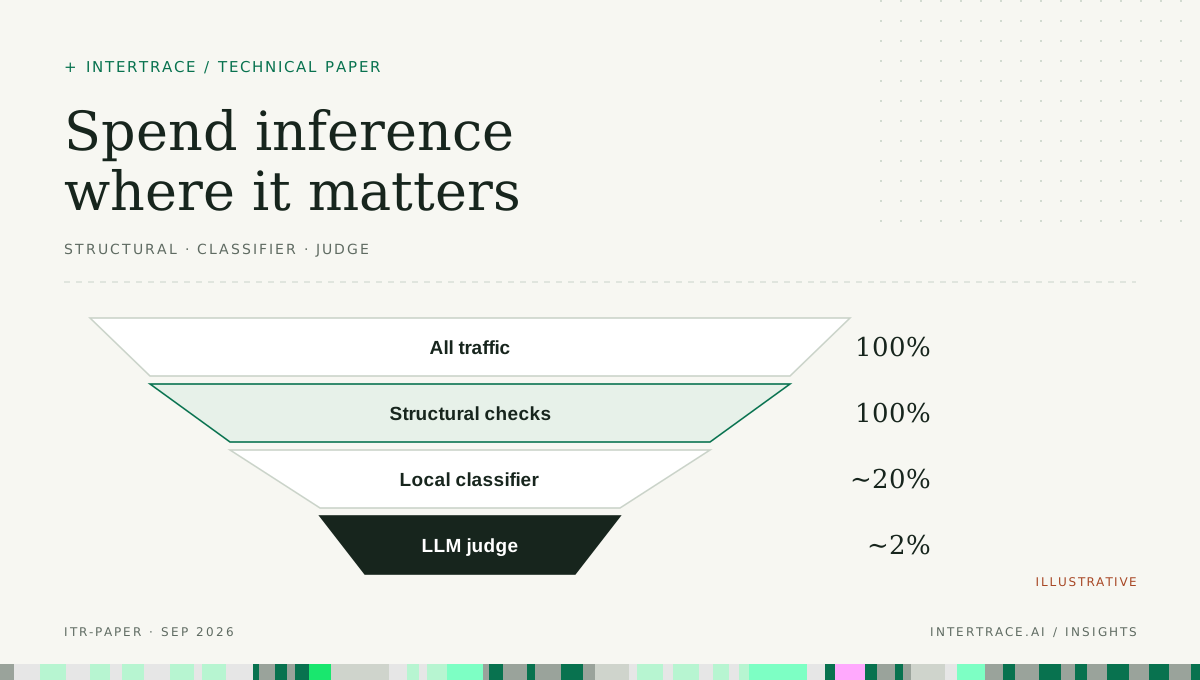
A cascade runs cheap checks on everything and expensive checks only on what the cheap ones cannot settle. The idea is established in model serving. FrugalGPT describes an LLM cascade that learns which combination of models to call for each query, and reports matching the best individual model with up to 98% cost reduction on its benchmarks [1]. Security detection suits a cascade even better than general question answering, because most traffic is plainly benign and the hard cases are rare.
All traffic passes structural checks in microseconds; the local classifier sees the illustrative ~20% carrying new free text, in milliseconds; the LLM judge sees about 2%, at hundreds of milliseconds. The shares are illustrative, but the shape is the point.
Tier 1: structural checks
Deterministic checks over the bytes of the request: hidden and zero-width characters, instruction text in fields that should hold data, encoded blobs, known token formats such as API keys, card numbers validated by checksum, and schema and size limits on tool arguments. They run in microseconds and are explainable. When they fire on a valid card number or an instruction hidden in a tool result, they are precise enough to act on alone.
Structural checks also decide what the next tier needs to read. In an agent loop, most of each request is context the gateway already scanned on an earlier hop. A tool call with structured arguments, or a turn whose only new text is a short reply, may leave nothing for a classifier to do. That is why, in the illustrative funnel, the classifier sees about a fifth of traffic rather than all of it.
Tier 2: local classifiers
Small models running next to the gateway: prompt-injection classifiers, PII entity detectors, intent routers. Meta's Prompt Guard 2 is a representative public example. Its model card describes an 86M-parameter model built on mDeBERTa-base and a 22M variant built on DeBERTa-xsmall, a 512-token context window, and measured latency of 92.4 ms and 19.3 ms per classification on an A100 GPU at 512 tokens [2]. Local is not free. At those figures a long tool result must be split into segments and scanned in parallel, as the card itself recommends, or the classifier becomes the slowest hop before the model [2]. The card also says to use it as one layer alongside other measures, not as a standalone defense [2].
Tier 3: the LLM judge
A general model asked whether content is an attack, a leak or a policy violation. It reads context the classifier cannot, and it costs far more per call in both money and latency. Reserve it for the residue: classifier scores in the uncertain band, content that precedes a consequential action, and cases where a cheap signal and the surrounding context disagree.
A worked cost model
The numbers below are illustrative assumptions, not measurements of any product or provider. Replace them with your own; the structure of the calculation is what transfers.
- Traffic: assume 2 million guarded calls a day, counting model calls and tool calls, over a 30-day month.
- Judge cost: assume $0.0005 per judged call, roughly 1,500 input tokens and a short structured verdict on a small hosted model.
- Judge latency: assume 400 ms at p50 and 1,200 ms at p99 for a judged call.
- Local classifier: assume a fixed $2,000 a month of edge compute, enough for the illustrative 20% of traffic it sees, at 15 ms p50 and 40 ms p99 after segment-parallel scanning.
- Structural checks: assume negligible cost and well under a millisecond.
| Design | Share sent to judge | Judged calls per day | Judge cost per month | Total with classifier |
|---|---|---|---|---|
| Judge every call | 100% | 2,000,000 | $30,000 | $30,000 (no classifier needed) |
| Judge everything the classifier sees | 20% | 400,000 | $6,000 | $8,000 |
| Judge only the uncertain residue | 2% | 40,000 | $600 | $2,600 |
| Tight cascade with decision fusion | 0.5% | 10,000 | $150 | $2,150 |
Two things fall out. Cost is linear in the escalation rate, so the escalation rate is the parameter to manage: a classifier update that moves it from 2% to 6% triples the judge bill without anyone touching the judge. And once escalation is low, the fixed classifier cost dominates and further judge savings stop mattering. That is the point to optimize the classifier's footprint instead.
Latency is where averages mislead. With 2% of calls judged at a 400 ms median, mean overhead rises by about 8 ms (0.02 × 400), which looks harmless on a dashboard. But 2% is more than 1%, so the p99 of all traffic falls inside the judged population: the p99 overhead is the judge's latency, not the classifier's. Cut escalation to 0.5% and the p99 returns to the classifier path, while the p99.9 still belongs to the judge. Google's SRE book makes the general case: most metrics are better treated as distributions, a simple average can obscure tail latency, and a high percentile such as the 99th or 99.9th shows a plausible worst case [3].
Inline or async: decide what must block
Not every check has to finish before the request proceeds. A check belongs inline only if its verdict changes what happens next and acting later would be too late. Everything else can run after the fact and alert, open a finding, or tighten policy for the next call.
| Check | Placement | Reason |
|---|---|---|
| Authentication and tenancy | Inline, blocking | Nothing should proceed under the wrong identity |
| Structural checks on requests and tool results | Inline, blocking | Microsecond cost, and high-precision signals can stop an injection before the model reads it |
| Authorization of consequential tool calls | Inline, blocking | A payment or deletion that has run cannot be recalled by an alert |
| Local injection classifier | Inline, flags or contributes to a decision | Cheap enough to run inline; precise enough to escalate, not always to block alone |
| LLM judge on uncertain content | Inline before consequential actions, async otherwise | Its latency is acceptable ahead of a payment and wasteful ahead of a read |
| Egress PII and secrets scan | Inline for responses leaving the trust boundary | Redaction has to happen before the data leaves |
| Session-level behavior analysis | Async | It needs many hops to see a pattern and acts on the next call or the session |
Streaming responses deserve a specific note. An egress scan that waits for the whole response defeats streaming. One that scans in windows can hold back a short tail of tokens and release the rest, and the window size is a latency-against-precision trade you should set deliberately rather than inherit.
Run independent checks in parallel
Illustrative, not measured: auth, structural checks and the classifier make up the security budget before the model, and the policy lookup runs in parallel with the classifier so the request waits for the slower of the two. The upstream model segment is not to scale.
Many checks do not depend on each other. Once the request is authenticated, the policy lookup for the agent's identity and the classifier score on new content can start together, and the decision waits for the slower one rather than their sum. Run checks in sequence only where one's output is another's input, as when a classifier score decides whether to call the judge.
Parallelism has a price: you spend compute on results you may not need, such as classifying a request that a structural check is about to block. At the cheap tiers that is almost always worth it. At the judge tier it is not. Start the judge only after the cheaper tiers have decided it is needed.
Give every check a deadline and decide its timeout behavior in advance. For blocking checks on consequential actions, the safe default is to fail closed and ask a person; for advisory checks, record the timeout and proceed. A judge without a deadline turns a provider slowdown into your outage.
Decision fusion: precision without judging everything
The most effective way to cut judge cost is to stop letting judge verdicts block on their own. Decision fusion gives each signal a role based on how it fails. Structural signals, such as a card number that passes its checksum or an instruction hidden in zero-width characters, are rarely wrong and may block alone. Model-judge labels like prompt injection or jailbreak are useful but contestable, so they flag by default and block only when an independent, cheaper signal agrees, such as an intent classifier or a structural hit.
The reason is measured judge behavior. Zheng et al. found that strong LLM judges reach over 80% agreement with human preferences, about the level humans reach with each other, while also showing position, verbosity and self-enhancement biases [4]. Their setting was grading chat answers, not security verdicts, but the lesson carries over: one judge label is an informed opinion with known biases, and blocking on one opinion turns each bias into a false positive on legitimate work.
Fusion also lowers the escalation rate. If a judge label alone cannot block a read-only call, there is little reason to judge read-only calls at all, and the judge's traffic narrows to content that comes before consequential actions.
Budget per hop, then per task
Set the guardrail budget as percentile targets per hop, then check what it means for a task. If guarded overhead is held to 25 ms at p50 and 80 ms at p99 per hop (illustrative targets), a twenty-hop agent task adds about half a second at the median. The task's tail is worse than any one hop's tail: across twenty independent hops, the chance that at least one lands in its own slowest 1% is about 18% (1 − 0.99^20). Budget the task as well as the hop, and give product teams that number before they measure it themselves.
Measure overhead as the difference between guarded and unguarded latency for the same call, recorded per check, and keep approval wait out of it. The time a person spends deciding an ask is a governance cost, not guardrail latency, and mixing the two makes both numbers useless.
Checklist: before a guardrail goes inline
- Write down the check's job: which decision it changes, for which consequence tier, and whether it must block or can alert.
- Measure its latency at p50, p95 and p99 on production-shaped inputs, including long tool results, and record the cost per call.
- Set a deadline and a timeout behavior: fail closed and ask for consequential actions, record and proceed for advisory checks.
- Place it in the cascade, estimate the share of traffic that reaches it, and alert when the observed share drifts well beyond that estimate.
- Run it in parallel with every check it does not depend on.
- Decide whether its verdict can block alone or needs a second signal, and test that rule against benign traffic that resembles attacks.
- Report guardrail overhead per hop and per task as percentiles, separately from approval wait, every month.
How Intertrace handles it
Intertrace runs the cheap tiers inside the gateway rather than as separate services: a local prompt-injection classifier and PII detection run on each edge machine next to the Go enforcer, so they add no network hop to another provider. Decision fusion is built in. Structural signals such as hidden instructions, instruction-override language and real tokens, card numbers or SSNs can block alone, while judge-only labels like prompt injection, jailbreak or secrets leakage flag unless a cheaper intent signal agrees. The enforcer fails closed when it cannot decide. Every decision is a structured event with its rule and evidence, so you can measure how often each signal fires and what it costs from your own telemetry instead of taking anyone's latency claims on trust.