The pattern is familiar to anyone who has rolled out an AI control. Security launches a gateway or an approval process, the dashboard shows traffic flowing through it, and the program is declared a success. A quarter later, the AI provider invoice is larger than the gateway's own usage numbers can explain. Someone traces the difference to personal keys on corporate cards, a team calling the provider directly from a batch job, and an evaluation pipeline that was moved off the gateway because, in the team lead's words, it kept blocking things and nobody could say why.
It is tempting to read that as a compliance failure. It is better read as a product failure. Every developer who routes around a control paid a cost the control's designers did not see. Fix the cost and most of the bypass disappears; enforcement then handles the remainder, which is much smaller and much easier to justify.
Why developers route around AI controls
Bypass has a small number of causes, and each has a specific design fix. Before you change anything, interview three teams that left the governed path and sort what they tell you into this table.
| Friction | What the developer experiences | What they do instead | Design fix |
|---|---|---|---|
| Setup cost | A ticket and several days of waiting for an API key | Create a personal key in the provider console | Self-serve keys in minutes, scoped to a project and an environment |
| A different API | An internal SDK wrapper with its own request shape that lags the provider's features | Call the provider SDK directly | Keep the provider's API and change only the base URL |
| Latency everywhere | Every call, including trivial ones, waits on the heaviest check | Turn the control off in development, then forget to turn it back on | Cheap checks for low-consequence calls; spend time where consequence is |
| Opaque denials | A bare 403 that says the request was blocked | Retry, rephrase the prompt, or switch paths | A denial with the rule, the reason, a decision ID and a next step |
| No exception path | A feature blocked for weeks waiting on a review | Ship a shadow deployment on a separate key | Self-serve, time-limited exceptions with a named owner |
| Feature gaps | Streaming, tool calls or a new model work directly but not through the control | Use the direct path for the features that matter | Treat feature parity as a requirement and publish the gaps |
Two of these do most of the damage in practice. Setup cost decides which path a new project starts on, and projects rarely move later. Opaque denials decide whether a team stays: a developer who hits three unexplained blocks in a week stops trusting the path, even if each block was correct.
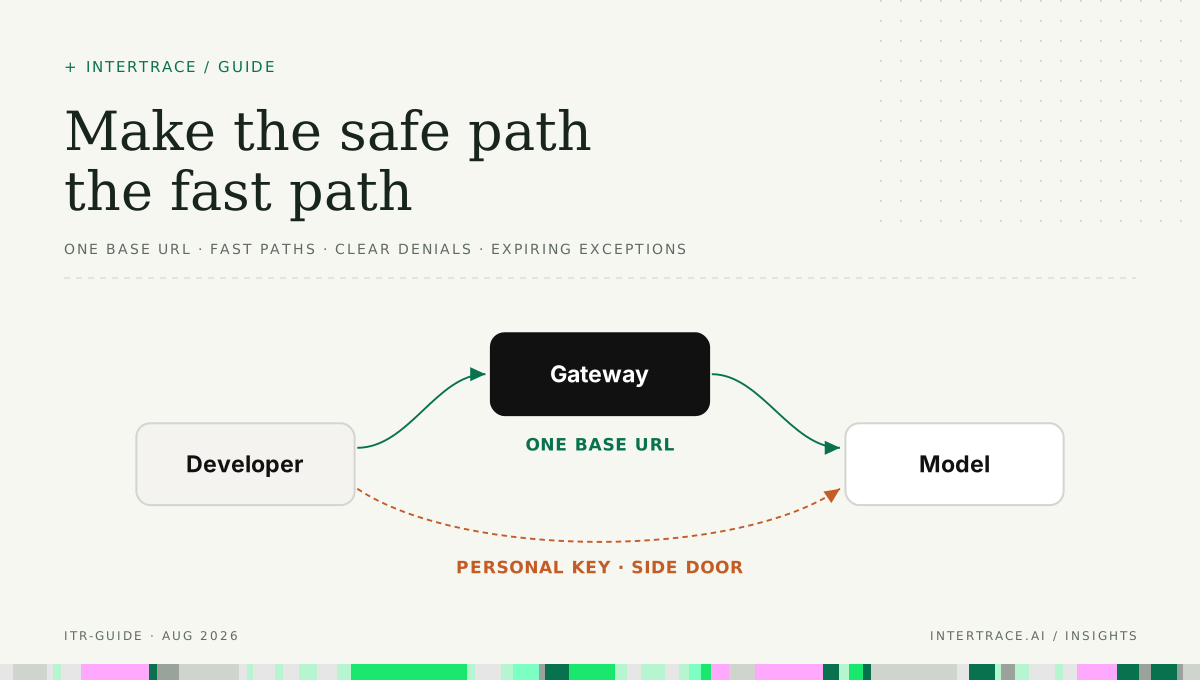
One base URL, same API
Make the governed path a configuration change, not a code change. Most model SDKs already let you point the client at a different endpoint. The OpenAI Python library, for example, accepts a base_url argument and also reads the OPENAI_BASE_URL environment variable [3]. If your control speaks the same API, a team adopts it by setting one variable and swapping one key, and every feature the provider ships keeps working unless you deliberately block it.
Do the same for tool traffic. If agents reach MCP servers and internal tools through the same front door as model calls, there is one endpoint to configure, one key to rotate and one place where policy applies. A separate integration for each kind of traffic multiplies the setup cost you are trying to remove.
- Put the governed base URL into every project template, internal starter kit and CI image, so a new service is on the governed path before anyone makes a choice.
- Hold provider credentials centrally and never hand them to developers. If the only working provider key lives behind the control, a personal key is not faster; it is a second account to set up and expense.
- Issue keys self-serve per project or per agent, tagged with an environment such as development or production, so policy can treat a test run differently from production traffic.
- Publish a one-page quick start that fits on a screen: the base URL, how to get a key, what is checked, and where denials are explained.
Fast paths: spend checks where consequence is
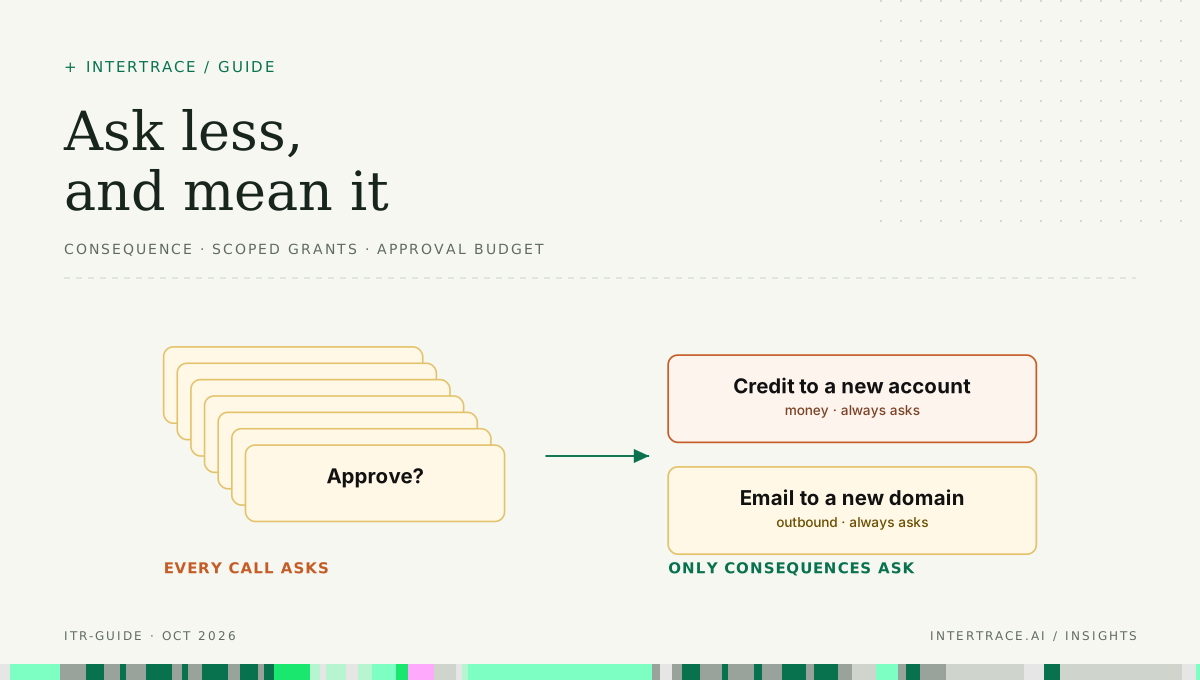
Not every call deserves the same scrutiny. A chat completion that summarizes an internal document and a tool call that deletes a production table are different risks, and a control that charges both the same latency will be resented on the first and under-powered on the second. Sort calls by consequence, meaning the worst realistic outcome of one call judged by reversibility and reach, and spend inspection where it changes outcomes.
Reads and reversible changes take a short path with cheap checks and run; irreversible, outbound, financial and administrative calls take the full path and may ask a person or be blocked. Most developer traffic never waits on the expensive path.
Environment matters as much as action. In development, an agent deleting a row in a disposable test database should not wait for a person. In production, the same call should. Outbound messages, payments and administrative changes are the exception: they reach the outside world or change who can do what, so they should ask everywhere, including in development, where a test message to a real customer is still a real message.
The fast path is not a weaker path. Structural checks, such as detecting real credentials or card numbers in a prompt, are cheap and should run on every call. What the fast path skips is the expensive work that only matters when a call can do damage.
A denial is a user interface
Most developers meet your control for the first time when it says no. That response is the control's user interface, and a bare 403 with the text request blocked is the worst one available. It tells the developer that something is wrong without telling them what, whether it is their fault, or what to do next. They rephrase the prompt, retry, and, when that fails, find another path.
HTTP already has a standard for this. RFC 9457 defines problem details: a machine-readable error body with a type URI that identifies the problem, a short human-readable title, a detail field specific to this occurrence, and an instance URI for the occurrence itself, and it allows problem types to add their own extension members [1]. Use it, and add the fields developers need to act.
The bare denial on the left gives the developer nothing to do but retry or leave. The structured denial on the right names the rule and the reason, says whether a retry helps, and links to the exception request.
- Name the rule and the layer that decided, for example an organization-wide data rule versus a rule specific to this agent, so the developer knows whom to talk to.
- Say what was found and where, without echoing the sensitive value: a value that looks like a card number in the third message, not the number itself.
- Say whether a retry can succeed. Policy denials will not change on retry; rate limits will. RFC 6585 defines 429 Too Many Requests for rate limiting and allows a Retry-After header saying how long to wait [2]. Keep the two distinct so client retry logic does the right thing.
- Return a decision ID that support and security can look up, so a developer can report a false positive in one message.
- Link to the next step: the documentation for the rule, the exception request, or the approval that is now pending.
Before a new rule blocks anything, run it in monitor mode and replay it against recent traffic. Count which teams it would have blocked and read a sample. A rule that would have denied a hundred legitimate calls a day is not ready, however sound its threat model.
Exceptions developers can request in minutes
Some denials will be correct in general and wrong for one team this week. If the only remedy is a security review with a two-week queue, the team will find another path. Make exceptions self-serve within limits instead, and make them expire.
- An exception is named, scoped to one agent or project, and carries a written reason and the requester's name.
- It has a default expiry measured in days and a hard maximum, so it cannot quietly become permanent.
- Low-consequence exceptions take effect immediately and are reviewed afterward; exceptions that touch outbound, financial or administrative actions need an approver before they apply.
- The agent's owner and the security channel are notified automatically, and every decision made under the exception records that it was the exception that allowed it.
- Exceptions that are renewed repeatedly are reviewed as evidence that the rule is wrong, not as evidence that the team is careless.
Measure bypass, don't guess it
The headline metric is governed share: the fraction of AI usage that goes through the control. The difficulty is the denominator, because bypassed traffic is by definition the traffic you do not see. Build it from several sources. AI provider organizations list keys and usage per key. Expense systems show subscriptions bought on cards. Egress logs and DNS show which hosts call provider API domains. Identity providers show OAuth grants to AI applications. Repository scanning finds committed keys; GitHub secret scanning, for example, lists both OpenAI and Anthropic API keys among its supported patterns [4].
| Metric | How to compute it | Healthy direction |
|---|---|---|
| Governed share of spend | Spend through the control divided by total provider spend across all organizations and expensed accounts | Rising toward nearly all |
| Keys outside the control | Provider keys not issued through the control, from provider org listings and repository scans | Falling, with each one assigned an owner |
| Time to first governed call | Minutes from a new project's key request to its first successful call | Short enough that nobody looks for a shortcut |
| Denials overturned | Share of denials later reversed as false positives or granted an exception | Low and falling; a spike means a bad rule |
| Time from denial to resolution | Minutes from a denial to a successful call or a granted exception | Falling |
| Exception renewals | Exceptions renewed more than once for the same rule | Each renewal reviewed as a rule defect |
When you find a bypass, contact the team before you revoke anything. Ask what they were trying to do and what stopped them on the governed path. Most answers map to a row in the friction table, and fixing that row helps every team rather than one.
A worked example: the platform team at Hollin Freight
Consider Hollin Freight, a fictional logistics company with forty product teams. All numbers in this example are illustrative. A central platform team ran an AI gateway that required a ticket for a key, which took about four days. It shipped a custom SDK that did not support streaming, and its denials returned a generic message. A discovery pass found twenty-three provider keys that had never been issued through the gateway, and the finance team estimated that a little over half of AI spend went through it.
Over one quarter the platform team changed five things, in this order. Keys became self-serve with a development or production tag. The custom SDK was retired in favor of the provider's own SDK pointed at the gateway's base URL, which brought streaming and tool calls back. Denials adopted the problem-details format with rule, reason, decision ID and an exception link. New rules spent two weeks in monitor mode before enforcing. And teams could grant themselves a seven-day exception for low-consequence rules, with a notification to security.
Only after those changes did the team close side doors. It gave every owner of an outside key thirty days' notice, offered to migrate their workloads, then revoked the remaining keys in the provider organizations and blocked provider API domains from production networks. By the end of the quarter, governed share was above ninety percent, time to first call was under ten minutes, and the most common exception had exposed a rule that flagged internal shipment IDs as card numbers. The rule was fixed and the exception stopped being requested.
What Hollin did not do matters too. It did not announce enforcement first, it did not name teams in an all-hands, and it did not treat the twenty-three keys as policy violations. Blocking first would have pushed the same workloads onto laptops and personal accounts, where nothing can see them.
Close the side doors last
Enforcement is still necessary; it just comes last. Once the governed path is the easier one, restrict egress to provider API domains from production networks, revoke provider keys that were not issued through the control, turn on push protection for provider keys in your repositories, and decline AI subscriptions on expense reports that duplicate a governed service. Announce each step with a date and a migration offer. Each one now removes an inferior option instead of the only working one.
What to do this quarter
- Interview three teams that left the governed path and sort their reasons into the friction table.
- Measure governed share of spend from provider organizations, expense data and repository scans, and record a baseline.
- Make keys self-serve and put the governed base URL into every project template and CI image.
- Adopt a structured denial format with rule, reason, retry guidance, decision ID and next step, and test it by showing three developers a denial and asking what they would do.
- Put every new rule through monitor mode and a replay against recent traffic before it enforces.
- Launch time-limited, self-serve exceptions for low-consequence rules and review renewals monthly.
- Only then set dates for revoking outside keys and restricting egress, and track the metrics table monthly.
Where a runtime gateway helps
A runtime gateway can carry most of the design above. With Intertrace, teams change their base URL and use a runtime key, and the same front door covers model calls, MCP traffic and agent-to-agent messages. The gateway assigns each call a consequence tier from the tool name and its arguments, so reads and reversible changes run while outbound messages, payments and administrative changes ask a person. Each decision records the rule and the layer that made it, exceptions are named, scoped to one agent and expire after seven days by default and ninety at most, and a proposed rule can be replayed against the last thirty days of real decisions before it blocks anything. The work of interviewing teams and closing side doors remains yours.