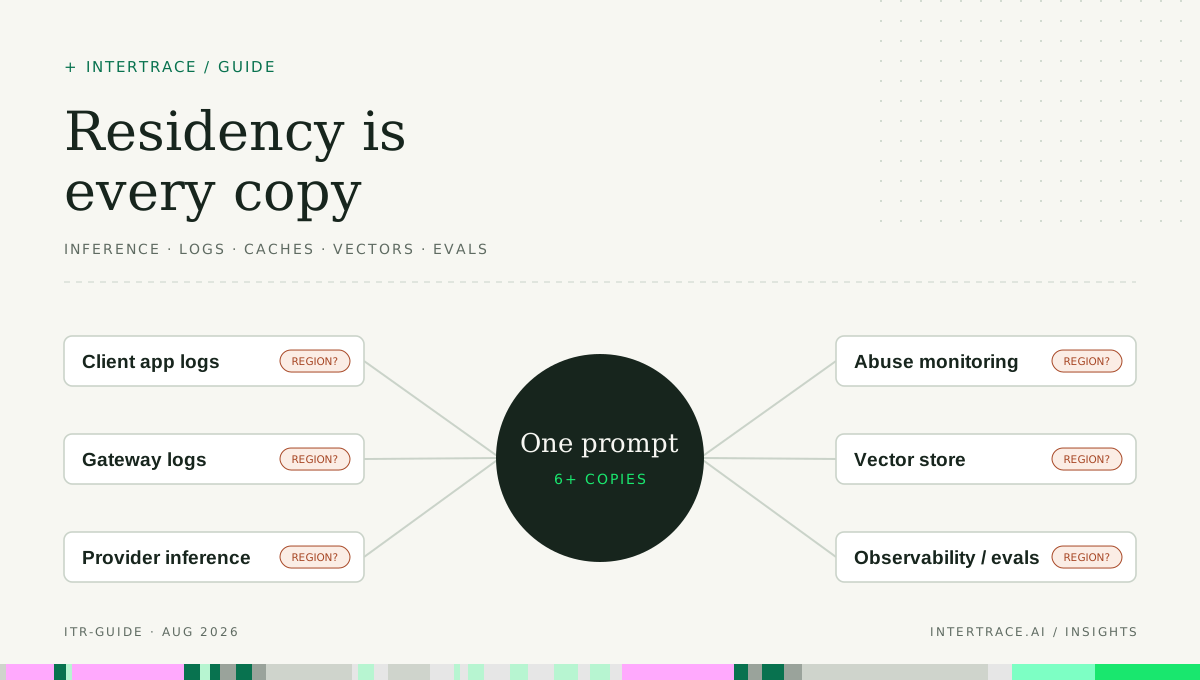
Most residency reviews of an AI feature end with one question: is the model endpoint in the EU? It is the wrong place to stop. By the time a prompt reaches the model it has been written to an application log, passed through a proxy, and possibly embedded into a vector store. After the model answers, the exchange may sit in a provider's abuse-monitoring store, an observability backend and the dataset someone is building for next month's evaluation. Residency is a property of every copy, not of the endpoint.
This guide maps those copies, explains what provider regional options actually cover, gives a high-level view of the GDPR transfer frame, and walks through routing by data class for a fictional EU insurer. It is not legal advice; your privacy counsel decides what your obligations are. The goal is to give them an accurate map.
Processing, storage and access are three different locations
Three locations matter for every copy, and providers often commit to them separately. Processing location is where compute touches the data: the GPUs running inference, or the service computing an embedding. Storage location is where data rests: logs, caches, stored conversations, files. Access location is where the people and systems that can read the data sit, including support staff and abuse reviewers.
The EDPB's recommendations on transfers make the third point explicit: remote access from a third country, for example in support situations, and storage in a cloud outside the EEA are also considered transfers [4]. An endpoint that processes in Frankfurt but lets reviewers elsewhere open stored prompts is not a purely in-region system.
Each spoke is a separate copy with its own location, retention and access list. Every one carries a region question, and the inference endpoint answers only one.
An inventory of copies
Build this table for each AI feature before deciding anything else. The "who sets the region" column is the one that surprises people: you control most copies, which means residency failures are usually your own.
| Copy | What is stored | Who sets the region | Common failure |
|---|---|---|---|
| Client app logs | Request bodies, errors, stack traces with prompt text | You | Debug logging ships prompts to a global log service. |
| Gateway or proxy logs | Full requests and responses, or metadata | You or your gateway vendor | Payload logging enabled by default. |
| Provider inference | Transient processing of prompt and output | Provider, by endpoint and deployment type | A global deployment type processes anywhere. |
| Provider abuse monitoring | Prompts and outputs retained for review | Provider terms | Assumed off; it is on by default for many accounts. |
| Prompt and response caches | Cached prefixes or responses | Provider and you | Extended caching processed outside the region. |
| Provider stateful features | Stored responses, threads, files, batches | Provider, by feature | A feature excluded from residency terms. |
| Vector store and embeddings | Chunks of source documents plus vectors | You | Managed vector database in a default region. |
| Observability and evals | Traces, prompts, labeled datasets | You or your tooling vendor | Production prompts copied into a global eval tool. |
Two copies deserve emphasis. Treat embeddings as personal data whenever their source text is; they sit beside the source chunks they index, and those chunks are often the most sensitive text in the system. Evaluation datasets are built from production traffic precisely because it is realistic, which means they inherit its personal data, then get exported, shared with vendors and kept indefinitely.
What provider regional options cover, and what they exclude
Read the provider's own data documentation, and read the exclusions as carefully as the headline. Two examples, as their documentation stood when this guide was written. Terms change, so verify against the current pages.
OpenAI's API data documentation says abuse monitoring logs are kept for up to 30 days unless longer retention is required by law, and that Zero Data Retention and Modified Abuse Monitoring, which exclude customer content from those logs, need prior approval [1]. Its data residency table separates regional storage from regional processing: some regions offer both, and several (including the UK, Canada and Japan) offered storage at rest but not regional processing. European regional processing requires an approved arrangement such as Zero Data Retention or Modified Abuse Monitoring. The page also notes that residency does not cover system data such as account, usage and billing information, that extended prompt caching in regions without regional processing may process and temporarily store content outside the region, and that some endpoints, including Files, are not eligible for zero retention [1].
Microsoft's documentation for models sold by Azure says prompts and responses are processed within the customer-specified geography unless you use a Global or DataZone deployment type [2]. A Global deployment may process in any geography where the model is deployed; an EU DataZone may process in any EU member state. Data at rest, including the abuse monitoring store, stays in the resource's geography, and for EEA deployments the human reviewers are located in the EEA. Batch processing is a Global deployment type [2]. Modified abuse monitoring removes the storage and human review, and the documentation explains how to verify that through a `ContentLogging` capability set to false [2].
The pattern across both: processing and storage commitments are separate, reduced retention is an approved arrangement rather than a default, specific features and deployment types fall outside the commitment, and metadata is often excluded. None of that makes either option unsuitable. It means the setting you chose has to be recorded per feature, per deployment and per account, and checked.
The GDPR transfer frame, at a high level
For EU personal data, residency questions usually become international transfer questions. Chapter V of the GDPR (Articles 44 to 50) governs transfers to third countries: the general principle in Article 44, then adequacy decisions, appropriate safeguards, binding corporate rules, and derogations for specific situations [3]. A transfer is lawful when one of those bases applies, so data leaving the EEA is not automatically a violation, and data staying inside it does not settle every obligation.
The EDPB's six-step recommendations start with "know your transfers": map where personal data is located or processed by importers, including onward transfers by your processors to sub-processors, and verify that what you transfer is limited to what is necessary [4]. For LLM traffic that map is exactly the copy inventory above, and data minimization is the control that does the most work: a prompt that never contained the claimant's name cannot transfer it.
Route by data class, not by application
Applications mix data classes in a single feature, so routing per application forces the strictest path on everything or the loosest path on sensitive data. Route each request by the class of data it actually contains. A three-class scheme is enough for most teams; you can map it onto an existing classification policy.
Classification happens before any model is chosen. Public data can use any approved model, internal data goes to an in-region endpoint, restricted data is redacted or blocked, and logs stay in-region on every path.
- Public: published product information, public documents, code you already open-sourced. Any model on your approved list.
- Internal: business data without personal or regulated content, such as procedures and internal notes. Only endpoints whose processing and storage terms match your residency requirement.
- Restricted: personal data, special-category data, credentials, payment data, anything under contractual residency. Redact before it leaves your boundary, or block the request if redaction would break the task.
Classification has to be cheap and conservative. Combine what the application declares (this request carries a claim file) with what detectors find in the payload (identifiers, card numbers, health terms). When the two disagree, take the stricter class. When classification fails or times out, treat the request as restricted, because an unclassified prompt is one you cannot route safely. Classify responses as well: a model can echo restricted data back from context, and that response lands in the same logs and caches as the request.
Worked example: an EU insurer and its claims assistant
Consider Kestrel Mutual, a fictional insurer headquartered in the EU. Claims handlers use an assistant to summarize claim files, draft letters to claimants and find similar past claims. The first design used one global model endpoint, logged every request to the application's log service, embedded all past claims into a managed vector database, and copied a sample of production conversations into an evaluation tool.
The copy inventory found six locations, four outside the EU or of unknown region: the log service's default region, the vector database, the evaluation tool, and the model endpoint's processing location. Abuse monitoring was on by default. Claim files routinely contained names, policy numbers, bank details and medical reports.
- Classify at the gateway. Requests tagged as claim work are restricted by default; detectors confirm identifiers, IBANs and health terms. Policy wording and product questions are public.
- Redact restricted fields before egress. Names, policy numbers and bank details become stable placeholders; the mapping stays in-region and the response is re-identified after it returns.
- Block what cannot be redacted. Free-text medical narratives that the task cannot do without are blocked from any endpoint lacking regional processing and approved reduced retention, and handled by an in-region path or a person.
- Send internal and redacted traffic to an in-region endpoint whose processing, storage and abuse-monitoring terms were confirmed for this account and deployment type, with the setting recorded.
- Move the vector database and its source chunks to an EU region, and index redacted text where similarity search still works on it.
- Keep payload logs in-region with short retention; export only metadata to observability; build evaluation sets from redacted traffic and keep them in the EU.
Redaction carried its own risks, and the team tested for them. Placeholders were scoped to one conversation, so the same claimant did not get a stable token that a provider-side log could link across claims. Detector recall was measured on a labeled sample of real claim files, because a name written in lowercase inside a medical narrative is exactly what pattern detectors miss. And quasi-identifiers such as dates of loss, postcodes and rare diagnoses were reviewed with the privacy team, since together they can identify a claimant even with every name removed.
What did not change matters too. Handlers kept the same assistant. Most requests still reached a capable model, because redacted claim summaries remain useful. The main cost was placeholder handling in letter drafting, which needed re-identification to run before a handler saw the draft.
Verify residency instead of asserting it
Residency decisions decay. A new SDK version enables payload logging, an engineer switches a deployment type for capacity, a vendor adds a sub-processor. Test the system the way you would test any other control.
- Plant canary strings in test prompts and search every log, trace store, cache and eval dataset for them on a schedule. A hit outside an approved location is a finding.
- Restrict egress so the application and gateway can reach only approved model hostnames, and alert on any new AI provider destination.
- Record provider settings per account and deployment (endpoint, deployment type, retention arrangement, abuse-monitoring status) and diff them weekly against the approved baseline.
- Scan code and CI for direct provider calls and committed keys that bypass the gateway; every bypass is an unmapped copy.
- Re-read provider data pages and sub-processor lists at least quarterly, and when you adopt a new feature such as batch, files or stored conversations.
Where a gateway helps, and where it does not
Intertrace does not pin traffic or storage to a region and does not host models; region choices stay with you and your providers. What the gateway provides is the place to classify and enforce what may leave. It detects and redacts PII and secrets in requests and responses, applies DLP to tool-call arguments, and can block a request carrying a restricted class, with an organization data policy as a floor individual agents can tighten but not loosen. Its OpenTelemetry fan-out carries metadata only, and discovery scans repositories, CI and AI provider organization keys for AI usage that may bypass the gateway. The gateway is also a processor that sees prompts, so include it in your copy inventory like any other.
What to do this quarter
- Build the copy inventory for your two highest-volume AI features, with processing, storage and access location for each copy.
- Confirm each provider setting you rely on (endpoint, deployment type, reduced retention, abuse monitoring) for the exact account and feature, and record it.
- Adopt a three-class scheme, classify at the gateway, and default unclassified requests to restricted.
- Turn off payload logging outside your region, move vector stores and eval datasets in-region, and keep only metadata in observability tools.
- Add canary-string searches and an egress allowlist, and take the resulting map to your privacy counsel for the transfer analysis.