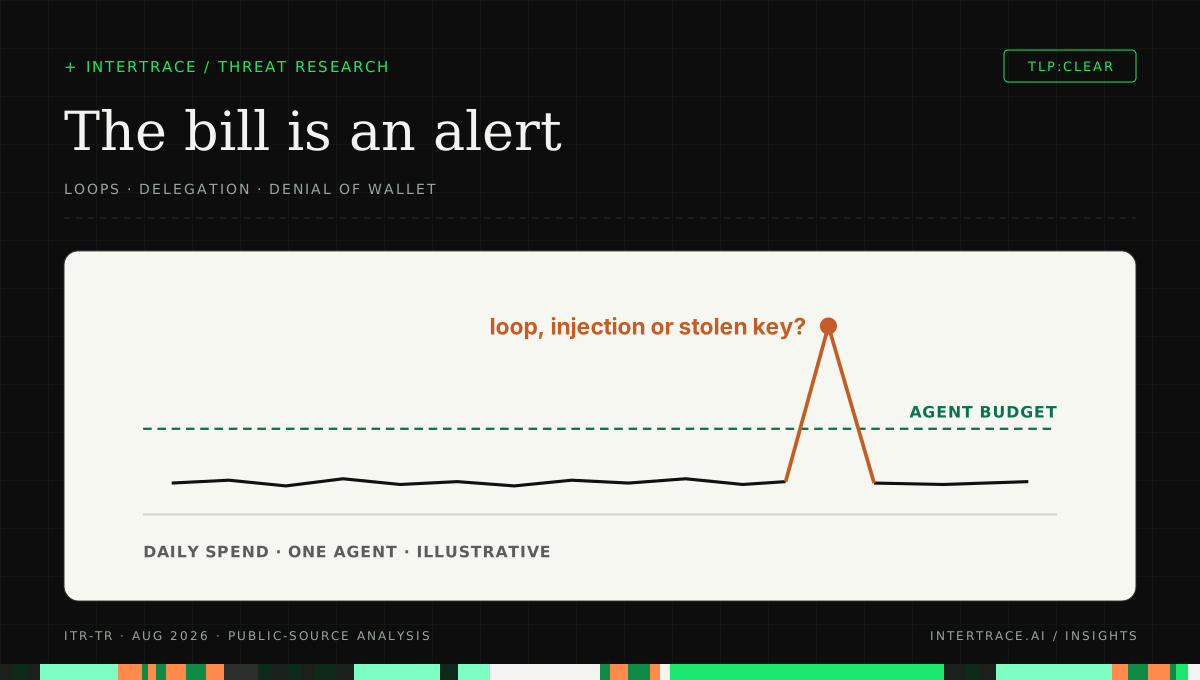
The pattern is familiar by now. The monthly invoice from a model provider comes in at three times the forecast. Finance asks engineering, engineering points at a busy month, and the conversation ends with a request to be more careful. Nobody asks security, because nobody thinks of a bill as an alert. Two weeks later someone notices that one agent made most of the calls, over a weekend, against a single web domain.
Cost is the one telemetry stream every agent produces whether or not anyone instrumented it. It moves for the same reasons security events do: something is running that should not be, something is running far more than it should, or someone has steered the agent into work nobody asked for. Treating spend as a security signal is mostly a matter of measuring it at the right granularity and deciding in advance who looks when it moves.
Four ways an agent burns money, and only one of them is growth
An agent's cost is the number of model and tool calls multiplied by what each one costs, and the second factor is dominated by tokens. Anything that multiplies calls or tokens without a matching business outcome needs an explanation. In practice the causes fall into four groups.
- Honest loops. The agent repeats steps it has already finished, or does not recognize when to stop. Cemri and colleagues' taxonomy of multi-agent failures lists both as distinct failure modes, step repetition and being unaware of termination conditions, under system design issues [4]. A tool that returns an error the agent cannot interpret is the usual trigger: the agent retries, rephrases and retries again.
- Recursive delegation. An orchestrator hands a task to a sub-agent that hands it back, or to a copy of itself. MITRE ATLAS describes adversaries forcing exactly this through self-delegation loops built from recursive definitions or repeated instructions [2]. Without a depth limit, the same thing happens by accident when a planner's prompt says to delegate anything it cannot finish.
- Injected consumption. Content the agent reads tells it to do more work. ATLAS lists directives such as translating a paragraph into all 50 major world languages or summarizing a text 1,000 times [2]. The OverThink paper shows a quieter version against reasoning models: decoy problems placed in the context an application reads raised reasoning tokens 46 times on one benchmark, and decoys in README files, skills and code raised them up to 17 times for coding agents, while the answers stayed correct [3].
- Someone else's usage. A leaked or resold key, an internal team borrowing another team's key, or deliberate volume aimed at the bill. OWASP calls the last case Denial of Wallet: driving up usage to exploit pay-per-use pricing and cause financial loss [1].
Only genuine growth explains a spike that comes with a matching rise in tickets resolved, documents processed or customers served. The other three groups share a signature: cost rises while the work completed per agent stays flat. That ratio, cost per unit of work, is the most useful number in this article.
What OWASP and MITRE call it
OWASP's LLM10:2025 Unbounded Consumption covers applications that allow excessive and uncontrolled inferences, with consequences that include denial of service, economic loss, model theft and degraded service [1]. Its examples include floods of variable-length input, repeated context-window overflow, resource-intensive queries and Denial of Wallet. Its mitigations read like a checklist for this problem: input size limits, rate limits and quotas per source, timeouts and throttling for expensive operations, monitoring for unusual consumption, and graceful degradation under load [1].
MITRE ATLAS files the same behavior under Cost Harvesting (AML.T0034): deliberately driving a victim's AI services beyond normal capacity to raise its costs, through many cheap queries or a few expensive ones [2]. ATLAS separates this from resource hijacking, where the attacker wants your compute for its own purposes; cost harvesting is pressure meant to cause financial harm [2]. Its sub-technique for agents, Agentic Resource Consumption, describes prompt injection or poisoned tool data that pushes an agent into unnecessary API queries, excessive fan-out or many distinct tool calls [2].
OWASP's Excessive Agency entry adds the operational point. It recommends rate limiting to reduce the number of undesirable actions, so that monitoring has time to catch a problem before major harm occurs [5]. Rate limits are not only a cost control. They buy time for every other control you have.
Why the provider's spend cap is the wrong circuit breaker
For most teams the only hard stop is the cap at the model provider, and it sits at the wrong level. Anthropic's documentation is a clear example: spend limits set a maximum monthly cost for an organization, and once the cap is reached, API usage pauses until the first day of the next month [6]. Requests then fail with an HTTP 429 that carries no retry-after header, and retries, including the SDK's automatic ones, keep failing until access resumes [6]. You can set lower spend and rate limits per workspace, but organization-wide limits always apply [6].
That design is reasonable for a provider protecting customers from surprise bills. For you it means the breaker trips the whole building. When one research agent loops overnight and exhausts the cap, the support agent and the billing agent stop with it. Before the cap trips, the runaway agent also eats into the shared per-minute rate limits, so well-behaved agents start seeing errors first. A cap that stops everything is a last-resort guard, not containment.
With only an organization-wide cap, one looping agent exhausts it and every agent stops. With a budget per agent in front of the provider, the looping agent's breaker trips and the other two keep running.
The fix is to add breakers below the provider's, at a level where agents and sessions can be told apart. A per-agent and per-session limit, enforced on the request path before the call reaches the provider, lets the runaway session stop while everything else keeps working.
A worked example: the overnight research agent
Consider Tidewell Advisory, a fictional consulting firm of 400 people. Its research agent reads public filings and news about a client's competitors, delegates page fetching and summarizing to a sub-agent, and writes a brief. On a normal task it makes about 40 model calls and 25 web fetches and costs around $0.60. All figures in this example are illustrative.
On a Friday night an analyst queues a brief on a mid-size competitor. One page the fetcher retrieves contains a block of text, invisible on the rendered page, telling any AI assistant to verify each figure by re-fetching every cited source and to translate its findings into twelve languages for regional teams. The planner obliges. Several cited sources return errors, so the fetcher retries. The planner, seeing incomplete results, delegates the verification again, and the sub-agent does the same.
By Saturday morning the session has made about 19,000 model calls and 7,000 fetches, most of them to one domain. At 06:10 the organization's monthly spend cap is reached. Tidewell's client-facing support assistant and its internal expense agent go down with the research agent, and the on-call engineer spends the morning on what looks like a provider outage. Security hears about it the following Wednesday, in a budget meeting.
Every signal needed to catch this early existed. Cost per brief went from under a dollar to several hundred. The same tool was called with the same arguments hundreds of times in one session. Delegation depth reached six on a workflow designed for two. And the cause was an injection, which means the same page could have asked for something worse than translation. A per-session budget would have stopped the session within minutes, a repetition signature would have flagged it before that, and a security review of the triggering page would have found the hidden text.
Detection: budgets, rates and loop signatures per agent
Detection works at three levels, and each catches something the others miss. Budgets catch slow burns that never look abnormal in any single minute. Rates catch bursts. Loop signatures catch the pattern while it is still cheap.
Budgets per agent and per session
Give each agent a daily budget and each session a ceiling, both derived from that agent's own history rather than a company-wide guess. A soft threshold flags and notifies the owner; a hard threshold refuses further calls in that session. Make the hard stop return a distinct, non-retryable error so the agent's retry logic does not hammer the limit, the same reason a provider's spend-cap error carries no retry-after header [6]. Per-agent budgets should add up under the organization's total so that no single agent can spend the whole month.
Rates and models per agent
Cap requests per minute per agent and per key, and cap tokens per call by limiting input size and output length, following OWASP's guidance on input validation, quotas and throttling [1]. Restrict which models each agent may use. A summarizer that suddenly calls the most expensive reasoning model is either misconfigured or being used by someone else.
Loop signatures
Loops have shapes you can compute from per-call records, provided each record carries the agent, the session, the tool, a hash of the arguments and the parent call or delegating agent. Three shapes cover most cases.
Repetition is the same tool with the same arguments hash in one session; self-delegation is an agent handing work to itself at growing depth; fan-out is one input producing far more calls than usual. Each is a query over per-call records.
| Signal | What it catches | How to compute it | Starting threshold (illustrative) | Common false positive |
|---|---|---|---|---|
| Cost per unit of work | Loops, injected work, misuse | Spend per agent divided by tickets, briefs or documents completed | 3x the agent's 30-day median | A genuinely harder batch of work |
| Session spend | Runaway sessions | Running cost per session ID | 10x the agent's median session | Long legitimate batch jobs; give them their own agent |
| Repeated identical calls | Retry and step-repetition loops | Count of the same tool and arguments hash in one session | More than 5 in 10 minutes | Polling tools; mark them as such |
| Delegation depth | Recursive and self-delegation | Longest chain of agent-to-agent hand-offs in a session | Deeper than the workflow's designed maximum | New workflows not yet baselined |
| Fan-out per input | Injected or runaway expansion | Tool calls per triggering message or ticket | 5x the agent's median | Bulk requests from a person; check who asked |
| Spend off pattern | Stolen or borrowed keys | Spend by key and hour against its history; keys with spend but no owner | Any spend from a key with no owner | Scheduled jobs; register them |
Start thresholds loose and tighten them as you learn each agent's normal. A signal that fires every day will be muted within a week, and a muted signal is worse than none because people believe it is watching.
Containment that stops one session, not the platform
When a signal fires, the goal is to stop the spend and keep the evidence without taking down agents that are working. The order matters.
- Stop the session, not the agent. Refuse further calls for the offending session and let other sessions of the same agent continue, unless the cause is shared, such as a bad tool or a poisoned knowledge source.
- Degrade before you kill. Where the business needs the agent running, move it to a cheaper model, turn off delegation and lower its rate, which is OWASP's graceful degradation applied to one agent [1].
- Revoke the key if usage does not match the agent. Spend from an unexpected network, at unexpected hours or on models the agent never uses points to someone else holding the key; rotate it and find where it leaked.
- Find the input. Pull the session's records, find the first call where behavior changed, and identify the content that came just before it: a retrieved page, a file, a tool response. If it was injected, open a security finding on the source, because the same channel can carry instructions with worse consequences than cost.
- Keep the records. Export the session's calls, decisions and triggering content before retention or cleanup removes them.
- Reconcile the bill. Give finance the session IDs, the cost of each and the cause, so the spike is explained with evidence rather than a guess.
What finance and security should look at together
Finance owns the budget and sees the bill first. Security owns the causes and usually sees them last. A 30-minute weekly review over one shared, per-agent view closes that gap, and it costs less than one bad weekend.
- Cost per unit of work for each agent, with a trend line. This is the number that separates growth from waste and the one finance can defend to a CFO.
- The ten most expensive sessions of the week, each with its agent, owner and a one-line explanation. An unexplained session in the top ten becomes a ticket.
- Spend by key, with an owner for every key. A key with spend and no owner is either shadow usage or a leak, and both belong to security.
- Signals that fired and how each was resolved, including false positives, so thresholds are tuned by people who see both sides.
Agree in advance who can change what. Finance should be able to lower a budget at any time. Raising one above the agent's baseline should take the agent's owner or security, and every raise should be recorded with a reason and an expiry date.
Test cases before you trust the controls
- Give a test agent a tool that always returns an error and an instruction to keep trying until it succeeds. Expected: the repetition signal fires, then the session budget stops the session with a non-retryable error, and other agents are unaffected.
- Put a benign inflation instruction in a test page, such as a request to repeat the summary in ten languages, and have the agent read it. Expected: fan-out per input is flagged and the page is recorded as the triggering content.
- Use an agent's key from an unfamiliar network outside working hours. Expected: the spend-by-key signal fires, and the key can be revoked without touching any other agent's key.
- Exhaust one agent's daily budget. Expected: that agent stops, every other agent continues, and the organization's provider cap is never reached.
- Make the source of cost data unavailable. Expected: you know whether your budget checks fail open or closed, and that choice is written down by someone who accepted it.
How Intertrace handles it
Intertrace sits inline between agents and the models, tools and MCP servers they call, and each agent calls with its own runtime key, so spend and decisions are attributed per agent and per session rather than per provider account. Per-agent limits narrow which models an agent may use, cap its requests per minute and set budgets that add up under the organization's, and a call over its limit is refused before it reaches the provider. Every decision is a structured event naming the agent, session, tool and outcome, which is the raw material for the cost-per-unit and loop signatures above, and events can be exported to your SIEM. Decision fusion flags hidden instructions and instruction-override language in content the agent reads, which is where injected consumption usually begins.